Trace Logomark

Our Data

Real-world activity – captured for robot learning, audited for quality and diversity, designed for research and training.
Three rings animating icon

Fueling the frontier of physical AI research

Motion & pose
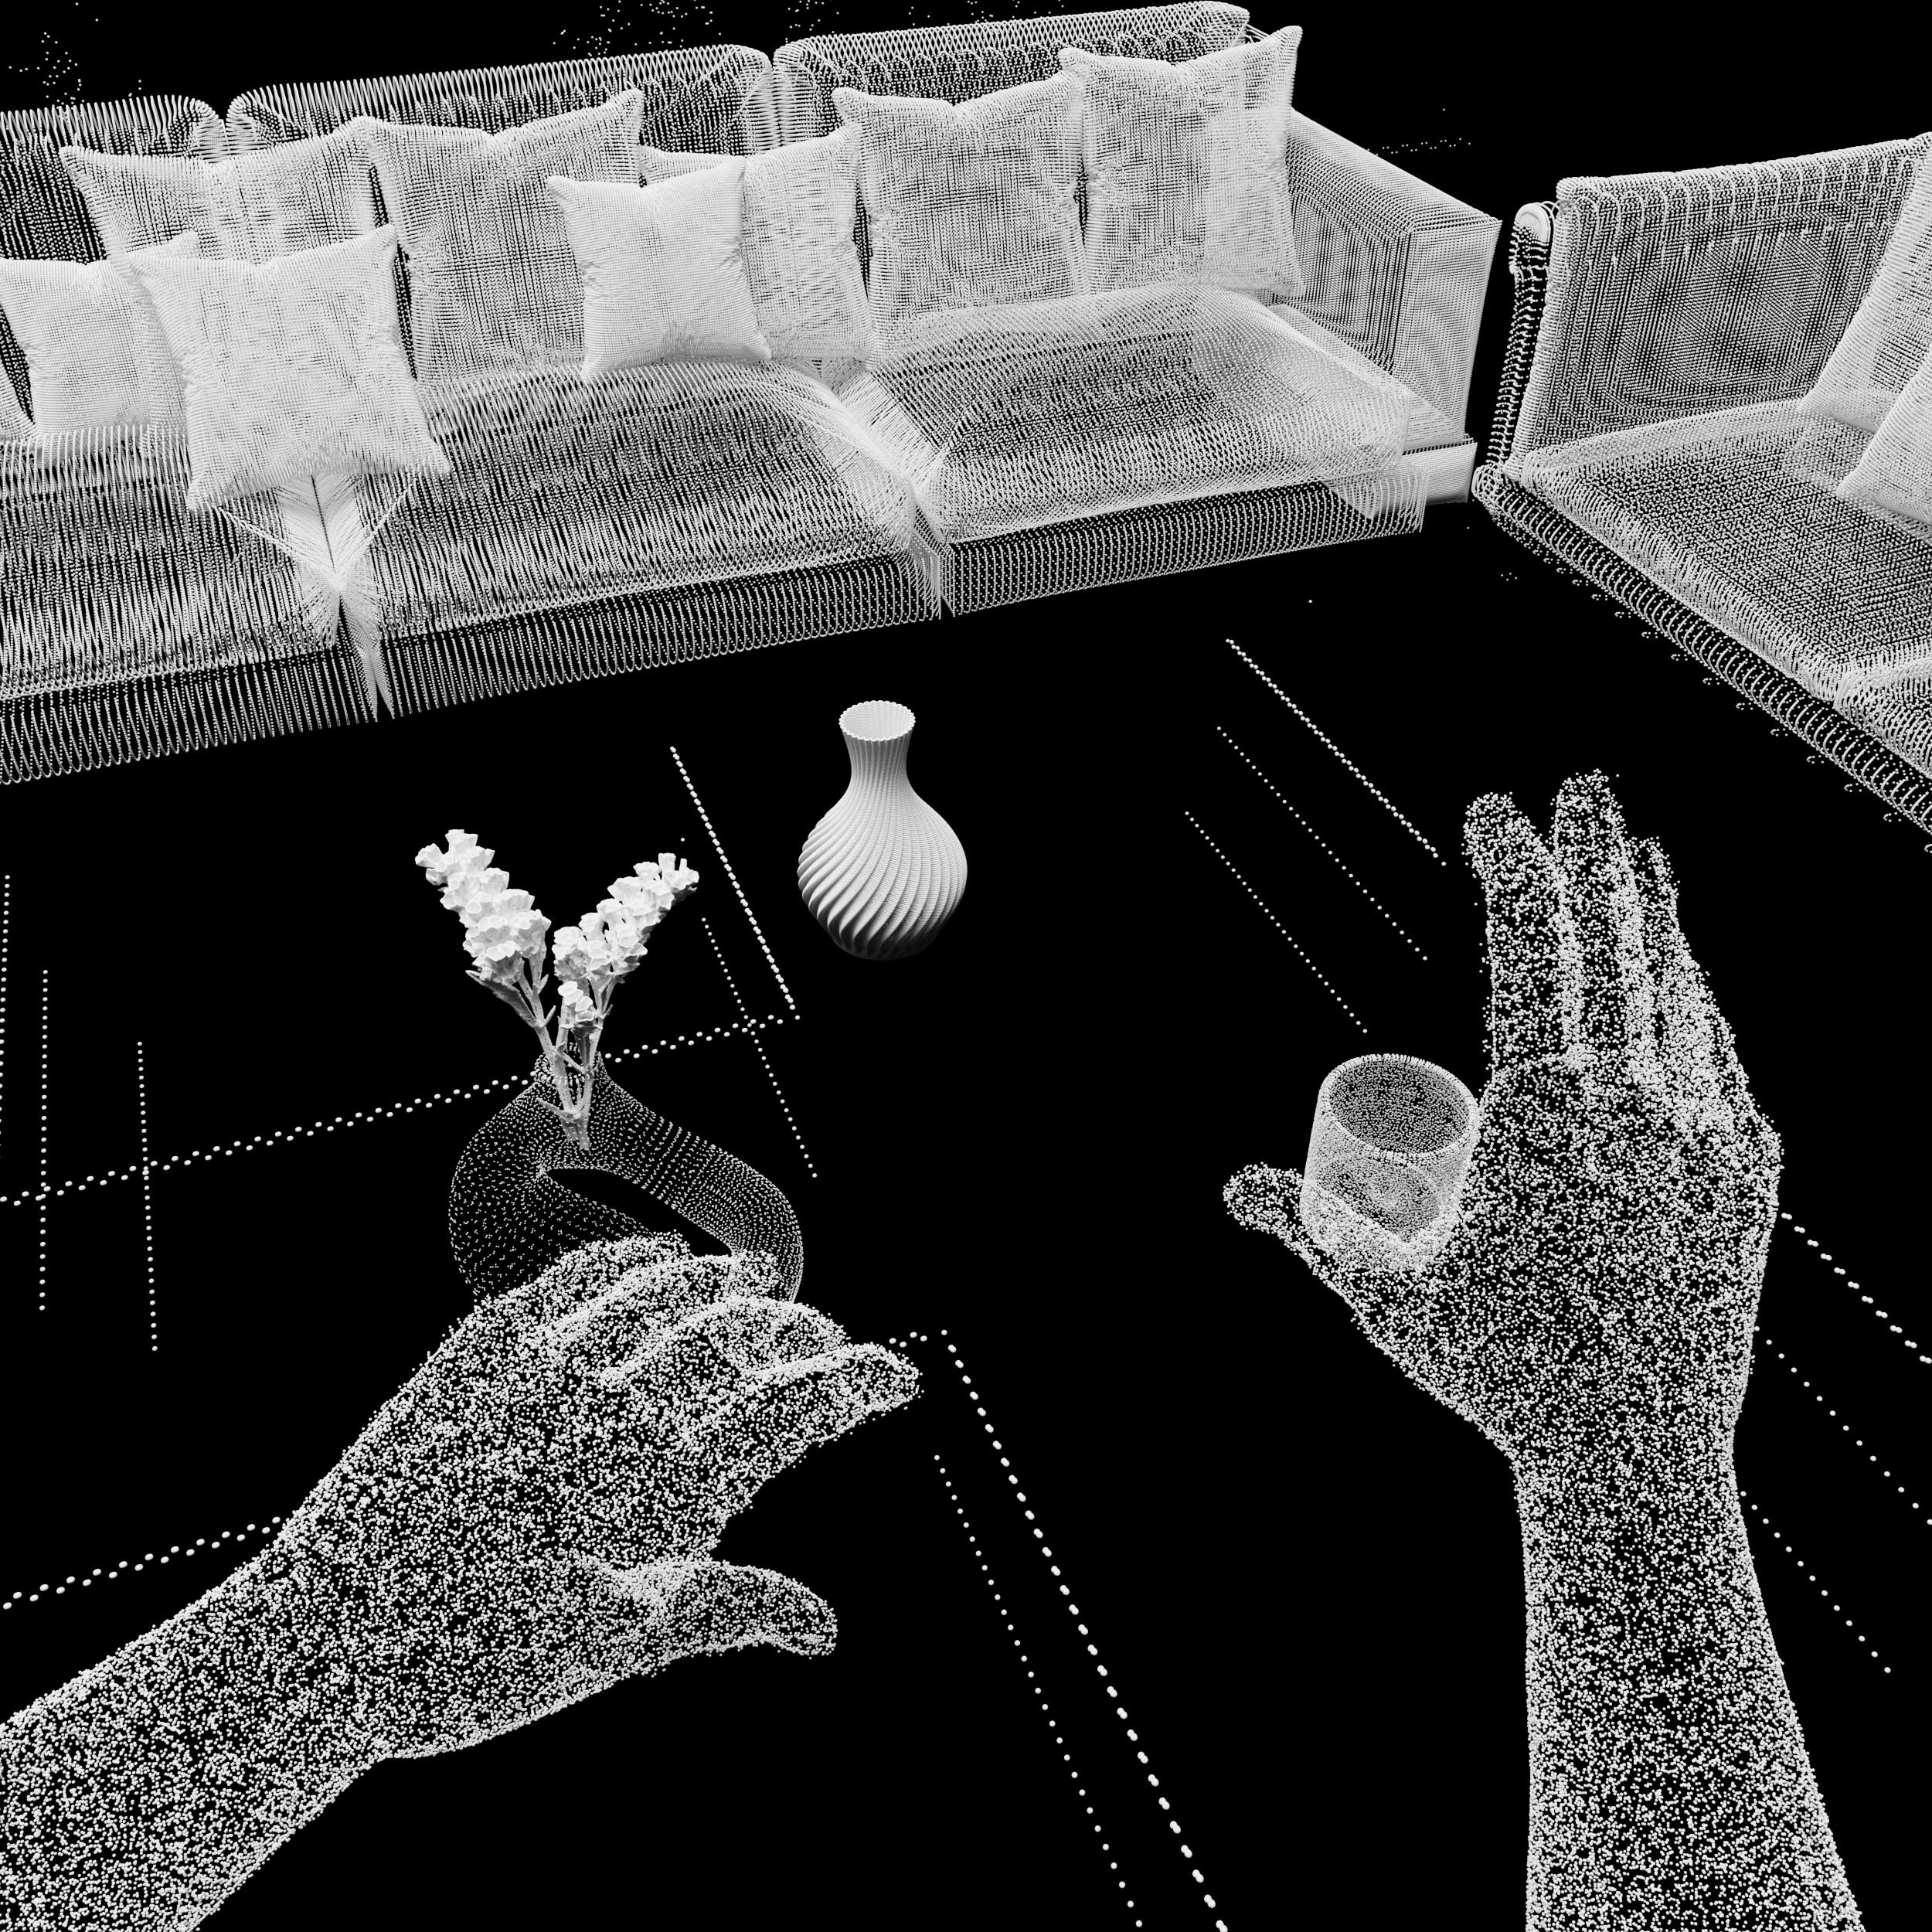
Hand and body pose tracked frame by frame, capturing not just what was done but exactly how – trajectory, timing, and contact of every action.
Depth & geometry
The 3D structure of the scene, so models learn the physical world in three dimensions, not flat pixels.
The real world
Source footage of genuine first-person activity, grounding every layer above it in reality rather than simulation.
 Open Research
Don't take our word for it. Use our data.
We believe data should be easy to use and inspect. Our datasets are densely annotated with accurate camera poses, 3D tracking, and frame-level language – and we believe in making it openly viewable, so researchers can judge quality for themselves before training on it.
Image representing EgoVerse
 Contributing to Egoverse
Trace data is part of Egoverse, the open consortium dataset for human-to-robot transfer led by Georgia Tech alongside Stanford, UC San Diego, ETH Zurich, and others.
Explore on Egoverse
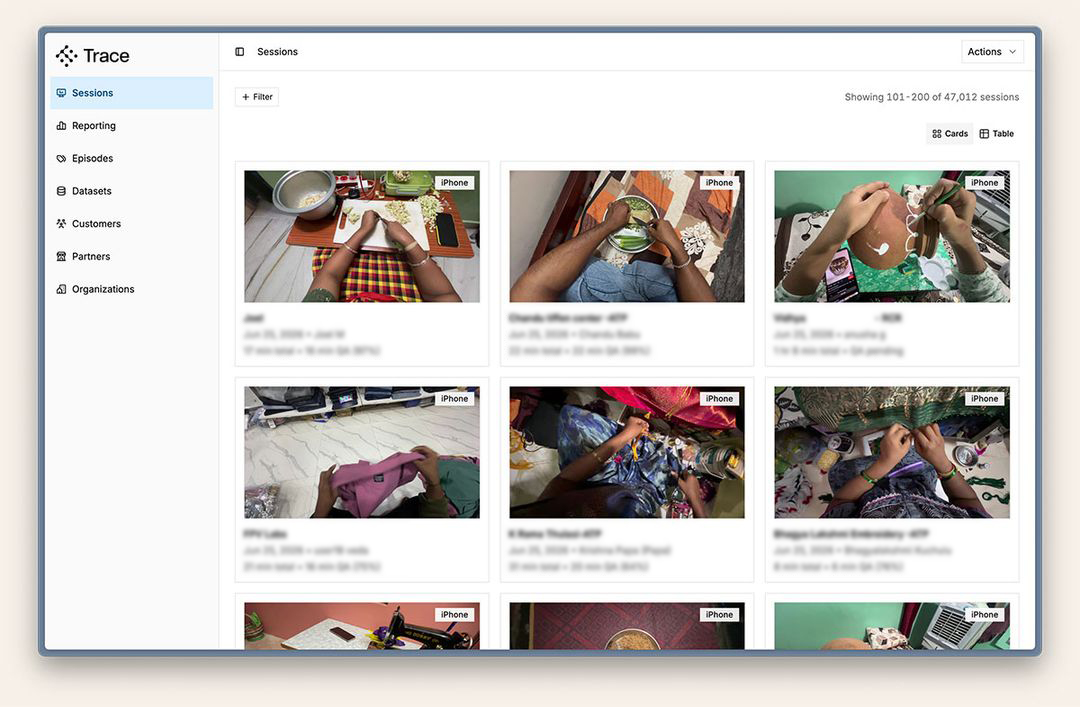
Trace Explorer screenshot
Browse in the Trace Explorer
An interactive window into our datasets – search by task, environment, and modality, and inspect individual episodes layer by layer. Don’t waste time downloading huge files or setting up layouts to view annotations properly.
Open the explorer
our tools
Purpose-built, multi-sensor capture.
We produce synchronized, multi-sensor data to translate the real world into useful training signals. We capture with human-worn sensors, UMI-style setups, and tele-operated devices, with sensors configured from simple RGB + IMU to depth, tactile, and more. The physical world doesn't fit one rig: we work with you to tailor capture modalities where the task demands it.
Icon box
Egocentric human capture, at scale
Lightweight, head-mounted capture that runs in real homes and workplaces – synchronized video, motion, and depth from the human point of view.
Icon scale
Multi-modal and richly annotated
We work with you to ensure sensors and post-processing will drive downstream performance in models – not data for data’s sake. We support many modalities of capture and annotation approaches, tailored to your goals.
FAQ
Frequently asked
Living room being captured.